
Yujiang Pu
3345 Engineering Building, 428 S. Shaw Lane, East Lansing, MI 48824
About Me
I’m a Ph.D. student (2023-) in the Department of Computer Science and Engineering (CSE) at Michigan State University (MSU), advised by Prof. Yu Kong in the ACTION Lab. Previously, I received my Master’s and Bachelor’s degree from the School of Information and Communication Engineering, Communication University of China (CUC), under the guidance of Prof. Xiaoyu Wu at the State Key Laboratory of Media Convergence and Communication (MCC).
I am engaged in research in Computer Vision (CV) and Machine Learning (ML), particularly in the area of vision-language perception and generation. My ultimate research goal is to enable intelligent systems to perceive, reason, and predict in complex visual environments. Specifically, my current research interests lie in:
- Controllable Video Generation: Developing controllable text/image-to-video frameworks, with interests in test-time optimization and compositional generation.
- Generative World Modeling: Scaling generative models to follow interactive instructions and integrate structured human knowledge for better prediction.
- Video Understanding & Reasoning: Leveraging foundations in action recognition and temporal grounding to interpret long-range event dynamics.
I am open to any communication and collaboration. Please feel free to contact me if you’re interested!
News
Selected Publications
-
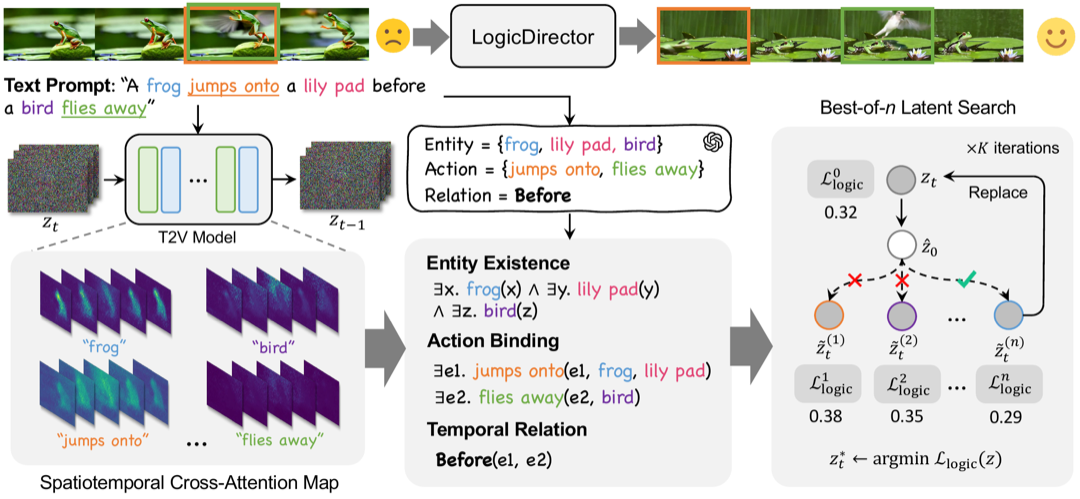 NeurIPS'26
Conference on Neural Information Processing Systems (NeurIPS), Dec. 2026.
-
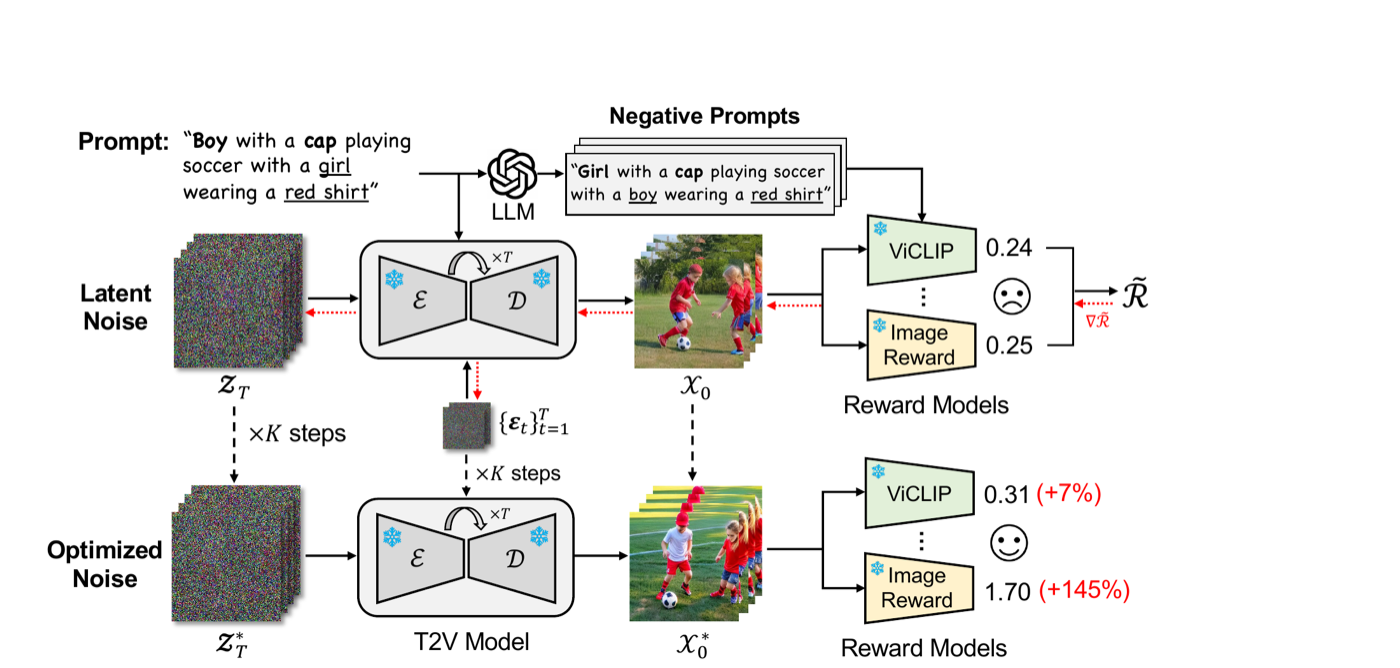 ECCV'26
European Conference on Computer Vision(ECCV), Sep. 2026.
-
 ICLR'26
International Conference on Learning Representations (ICLR), Apr. 2026.
-
 WACV'26
Winter Conference on Applications of Computer Vision (WACV), Mar. 2026.
-
 ECCV'24
European Conference on Computer Vision(ECCV), Jul. 2024.
-
 ICME'22
IEEE International Conference on Multimedia and Expo(ICME), Jul. 2022.
-
 ICCECE'22
International Conference on Consumer Electronics and Computer Engineering(ICCECE), Jan. 2022.
-
 IEEE TIP
IEEE Transactions on Image Processing (T-IP), Aug. 2024.
-
 Neurocomputing
 (NC), Dec. 2022.
Conference Papers
Journal Articles
Honors & Awards
- Outstanding Graduate Thesis, Communication University of China, 2023. (top 5%)
- The First-Class Academic Scholarship, Communication University of China, 2020-2022. (top 10%)
- Outstanding Graduate, Communication University of China, 2020. (top 10%)
Academic Services
Conference Reviewer
- The IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)
- International Conference on Computer Vision (ICCV)
- European Conference on Computer Vision (ECCV)
- Association for the Advancement of Artificial Intelligence (AAAI)
- International Conference on Learning Representations (ICLR)
- ACL Rolling Review (ACL ARR)
- Conference and Workshop on Neural Information Processing Systems (NeurIPS)
Journal Reviewer
- IEEE Transactions on Image Processing
- IEEE Transactions on Multimedia
- ACM Computing Surveys
- Journal of Visual Communication and Image Representation
Powered by Jekyll and Minimal Light theme.